If you give ChatGPT five reports and ask it to “summarize these sources,” the result may look excellent—and still misrepresent the research.
Imagine that you are preparing a market brief from a customer survey, a sales report, an industry study, a competitor analysis, and an analyst forecast. Three sources suggest demand is growing. One shows stagnation. Another predicts a decline in one specific segment.
A weak AI summary might reduce all of that to: “The sources generally indicate growing demand.” The sentence sounds reasonable, but it removes one of the most important things the research contained: disagreement.
This is not only a hallucination problem. ChatGPT can accurately read individual sources and still lose important distinctions when it combines them into one fluent narrative. Different findings can be blended together, minority evidence can disappear, and claims that belong to one source can start sounding like conclusions supported by all of them.
The safer approach is to separate analysis from synthesis. Label the sources, extract their claims, map where they agree and disagree, check whether apparent contradictions are real, and only then ask ChatGPT to write the final summary.
The core rule: do not ask ChatGPT to create one unified narrative until it has explicitly identified where the sources disagree. Otherwise, a fluent summary can hide uncertainty that was visible in the original material.
Why Summarizing Multiple Sources Is Different From Summarizing One
Summarizing one document is primarily a compression task. You take a longer piece of information, identify what matters, and produce a shorter version.
The basic process looks like this:
Document → important information → summary
Multi-source summarization is different because the model has to do more than shorten text. It has to understand the relationship between claims made by different sources.
A more reliable process looks like this:
Sources → claims → relationships between claims → synthesis
That distinction matters whenever the sources do not say exactly the same thing.
Suppose three reports discuss the effect of remote work on productivity:
- Source A: Remote work increased productivity by 12%.
- Source B: The study found no measurable productivity change.
- Source C: Individual task productivity improved, while collaborative work became less efficient.
A weak multi-source summary might say:
Remote work generally improves productivity.
That statement compresses three distinct findings into one conclusion. It removes the neutral result from Source B and the conditional result from Source C.
A more faithful synthesis would say:
The sources do not reach a single conclusion about the productivity effects of remote work. Source A reports an overall increase, Source B finds no measurable change, while Source C reports different effects depending on the type of work being performed.
Example: Three sources can discuss the same question and still measure different populations, time periods, or outcomes. A useful summary preserves those differences instead of converting them into artificial consensus.
This is the difference between simply summarizing multiple articles with ChatGPT and asking the model to perform actual source synthesis.
Why ChatGPT Can Lose Disagreement Between Sources
ChatGPT is very good at producing coherent prose. In multi-source research, that strength can also create a risk: the cleanest narrative is not always the most faithful representation of the evidence.
It Can Optimize for a Coherent Answer
When several sources point in slightly different directions, the model may produce a sentence that connects them smoothly. That often makes the output easier to read, but it can also make the research look more consistent than it really is.
For example, suppose one report says customer retention increased, another says it remained stable, and a third says retention improved only among enterprise customers. A polished summary may be tempted to conclude that retention “generally improved.” That is a stronger statement than the evidence supports.
Similar Claims Can Be Merged Too Aggressively
Two statements can sound similar without meaning the same thing.
“Sales increased slightly” is not equivalent to “sales were statistically unchanged.” “Most employees prefer hybrid work” is not equivalent to “hybrid workers report higher satisfaction.” “AI use increased” is not equivalent to “AI improved business performance.”
If those distinctions matter to your decision, they also need to survive the summary.
Source Attribution Can Disappear
After several sources are blended into a narrative, it can become difficult to tell which source supports which statement.
This becomes particularly risky when one source provides strong evidence and another contains only commentary or a prediction. If attribution disappears, the reader may assume that both claims have the same evidentiary basis.
Different Time Periods Can Look Like Contradictions
A 2024 report and a 2026 report may produce different results because conditions changed. A quarterly decline can exist alongside a positive annual trend. Historical performance and future expectations can also point in different directions without actually contradicting each other.
A good synthesis needs to preserve those time boundaries.
Different Definitions Can Create False Agreement or Disagreement
Sources may use the same word for different metrics.
One study might define productivity as tasks completed per hour. Another might measure revenue per employee. A third might ask workers to rate their perceived productivity.
If ChatGPT treats all three as the same variable, it can create either false agreement or false contradiction.
Practical rule: Before asking ChatGPT which source is correct, first ask whether the sources are actually answering the same question, using the same definitions, population, and time period.
How to Summarize Multiple Sources With ChatGPT: A Safer Workflow
The safest workflow separates the task into stages. The purpose is not to make the process unnecessarily complicated. It is to prevent the final synthesis from hiding information before you have had a chance to inspect it.
Step 1 — Define the Question Before Adding Sources
“Summarize these documents” is usually too broad for serious multi-source work.
A broad instruction gives ChatGPT substantial freedom to decide what matters. That can be useful for quick orientation, but it is risky when you need the summary to answer a specific business or research question.
Instead, define the question first.
For example:
Too broad: Summarize these reports about four-day workweeks.
Better: What do these sources say about whether a four-day workweek affects employee productivity?
The second version creates a common comparison point. Each source can now be evaluated against the same question.
I am going to provide multiple sources about [TOPIC].
The research question is: [QUESTION].
Do not summarize anything yet. First confirm the exact question that all sources should be evaluated against and identify any ambiguity in the question that could affect the comparison.
If your research question contains vague terms such as “effective,” “successful,” “better,” or “productive,” define them before proceeding. Otherwise, different sources may appear to answer the same question while actually measuring different outcomes.
Step 2 — Label Every Source
Before asking ChatGPT to compare anything, give every source a stable identity.
A simple structure works well:
[SOURCE A]
Title:
Author or organization:
Date:
Text or excerpt:

[SOURCE B]
Title:
Author or organization:
Date:
Text or excerpt:

[SOURCE C]
Title:
Author or organization:
Date:
Text or excerpt:
The labels do not have to be sophisticated. Their purpose is to stop claims from becoming detached from their origins.
Later, you want ChatGPT to say:
Source B reports no measurable change in productivity.
Not:
One of the reports suggests there was no change.
Stable source IDs also make it easier to audit the final result, because you can trace disputed claims back to the original material.
Step 3 — Extract Claims Before Writing a Summary
This is one of the most important parts of the workflow.
Do not ask ChatGPT to synthesize everything immediately. First force the model to analyze each source separately.
Analyze each source separately before attempting any synthesis.
For each source, extract:
1. Its main claim relevant to the research question.
2. The evidence it provides.
3. Important numbers or factual claims.
4. Qualifications or limitations stated by the source.
5. The population, geography, or time period if relevant.
Attribute every extracted claim to its source. Do not compare or reconcile the sources yet.
This intermediate step is valuable because you can inspect the model's reading of each source before those readings are blended together.
Suppose four documents discuss customer demand. ChatGPT might extract:
- Source A: Demand increased 14% year over year across all customer groups.
- Source B: Demand remained flat in the last quarter.
- Source C: Enterprise demand increased while small-business demand declined.
- Source D: Survey respondents expect demand to rise during the next 12 months.
At this stage, do not ask which source is right. You first need to understand how the claims relate to one another.
Step 4 — Build an Agreement and Disagreement Matrix
Once the claims have been extracted, convert them into a comparison matrix.
This makes relationships between sources visible before they disappear inside paragraphs.
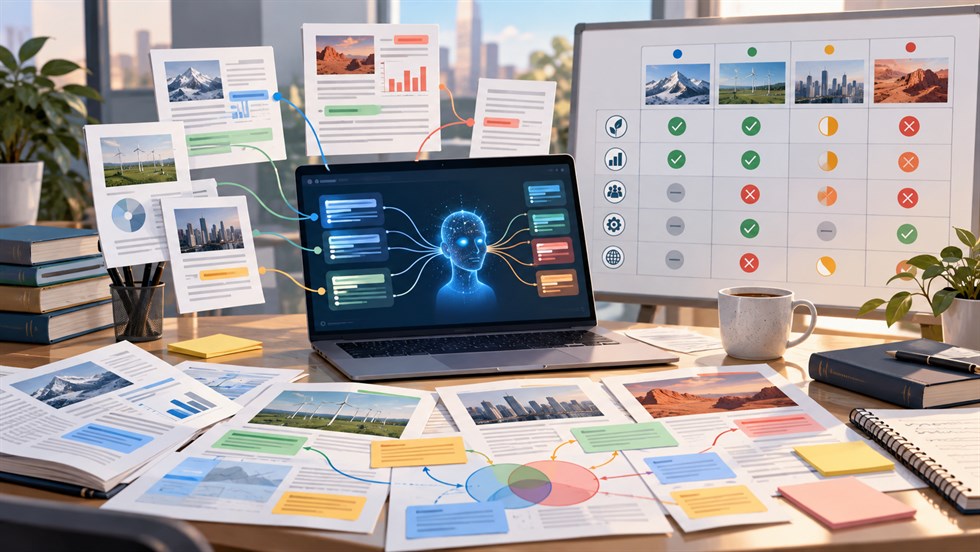
| Claim or Question | Source A | Source B | Source C | Relationship |
|---|---|---|---|---|
| Productivity increased | Yes | No measurable change | Only for individual tasks | Disagreement |
| Employee satisfaction improved | Yes | Yes | Yes | Agreement |
| Turnover decreased | Not covered | Yes | Partial evidence | Incomplete evidence |
A useful classification system includes at least five categories.
Agreement
The sources make claims that are materially compatible.
They do not need to use identical wording. If one source reports an 8% increase and another reports a 10% increase in a genuinely comparable measurement, both may support the same directional conclusion.
Partial Agreement
The sources agree on the core direction but differ on magnitude, scope, explanation, or conditions.
For example, two sources may agree that AI adoption is increasing, while disagreeing about whether adoption is concentrated in large companies or broadly distributed across the market.
Disagreement
The conclusions materially conflict.
One source may find that a policy improved productivity while another comparable study finds that it reduced productivity.
Not Comparable
The sources appear related but measure sufficiently different things that a direct comparison would be misleading.
A survey of U.S. software companies should not automatically be compared as equivalent evidence with employment data for all European industries.
Covered by Only One Source
A claim can be important even when only one source discusses it. The key is to preserve that fact instead of presenting the claim as if multiple sources supported it.
Create a comparison matrix for the sources.
For every material claim, classify the relationship as:
• Agreement
• Partial agreement
• Disagreement
• Not comparable
• Covered by only one source
For every disagreement, state exactly what each source claims. Do not resolve or average conflicting claims.
The phrase “do not resolve or average conflicting claims” is important. Without it, ChatGPT may try to be helpful by creating a compromise conclusion that no source actually supports.
Step 5 — Check Whether the Sources Really Contradict Each Other
Not every difference is a disagreement.
Before treating two statements as conflicting evidence, ask why they differ.
Common explanations include:
- different publication dates;
- different geographic markets;
- different sample sizes;
- different customer segments;
- different definitions;
- different research methodologies;
- forecasts versus observed results;
- correlation versus causation;
- primary evidence versus secondary commentary.
Consider these two claims:
Source A: 60% of companies plan to increase AI spending next year.
Source B: AI spending declined 4% during the previous quarter.
At first glance, they point in opposite directions. But they are not necessarily contradictory.
Source A describes future intentions. Source B describes past actual spending. Both statements can be true at the same time.
A weak synthesis might write:
Evidence about AI spending is mixed.
A stronger synthesis would explain:
Recent spending declined, while survey data suggests many companies expect to increase spending in the coming year. The sources describe different time periods and different types of evidence, so the findings should not be treated as a direct contradiction.
Do not confuse difference with contradiction. Two sources may report different results because they measure different periods, populations, definitions, or outcomes. Those differences belong in the summary too.
Step 6 — Ask ChatGPT to Write the Synthesis
Only after the claims and disagreements are visible should you ask ChatGPT to produce the narrative summary.
The goal is not to write one paragraph for Source A, another for Source B, and another for Source C. That is source-by-source summarization, not synthesis.
The final answer should organize the evidence by what it says about the research question.
Using the claim analysis and comparison matrix above, write a concise synthesis answering [RESEARCH QUESTION].
Structure it in this order:
1. What the sources broadly agree on.
2. Where the evidence is mixed or qualified.
3. Where the sources directly disagree.
4. Important claims supported by only one source.
5. What cannot be concluded from these sources.
Preserve source attribution for disputed or source-specific claims. Do not create consensus where the sources do not support it.
For example, suppose the evidence shows:
- two studies found increased productivity;
- one found no overall change;
- one found gains only in individual work;
- all four found higher employee satisfaction.
A poor synthesis would say:
The research shows that remote work improves both employee satisfaction and productivity.
A better synthesis would say:
The sources consistently associate remote work with higher employee satisfaction, but the evidence on productivity is less consistent. Two studies report overall productivity gains, one finds no measurable change, and another finds gains primarily in individual rather than collaborative work. The available evidence therefore supports a more consistent conclusion about satisfaction than about overall productivity.
The second version is slightly less tidy. It is also much more useful.
Step 7 — Run a Disagreement Audit
Even after a careful workflow, important differences can disappear during the final writing step.
That is why the final summary should be audited separately.
A Disagreement Audit asks ChatGPT to compare its own synthesis with the source analysis and identify places where it may have smoothed over conflicting evidence.
Audit the summary you just wrote against the original sources.
Identify:
1. Any disagreement from the sources that disappeared from the summary.
2. Any sentence that combines incompatible claims.
3. Any source-specific claim presented as general consensus.
4. Any conclusion stronger than the evidence supports.
5. Any statement whose source attribution is unclear.
Return the problems first. Then provide a corrected version of the summary.
This step is especially valuable when the final output is short.
The shorter the summary becomes, the stronger the pressure to compress nuance. A two-page research brief may have room to explain three competing interpretations. A five-bullet executive summary may not.
The Disagreement Audit forces the model to check what was lost during that compression.
A Complete Copy-and-Paste Prompt
If the task is relatively small, you can combine the workflow into one structured prompt.
For important research, however, running the stages separately is usually safer because you can inspect the output after each step.
I will provide several sources addressing the same research question.
Research question: [QUESTION]
Analyze the sources in stages:
Stage 1 — Claims
Extract each source's relevant claims, evidence, numbers, scope, date, and stated limitations.
Stage 2 — Comparison
Group the claims into agreement, partial agreement, disagreement, not comparable, and single-source claims.
Stage 3 — Disagreement check
For every apparent disagreement, check whether it could result from different definitions, populations, methodologies, or time periods.
Stage 4 — Synthesis
Write one concise summary answering the research question. Preserve meaningful disagreements and attribute disputed claims to their sources.
Stage 5 — Audit
Compare the synthesis with the original sources and flag anything that was generalized, omitted, strengthened, or reconciled without sufficient evidence.
Do not invent information that is absent from the supplied sources. If the evidence does not support one conclusion, state that explicitly.
[SOURCE A]
[PASTE SOURCE]
[SOURCE B]
[PASTE SOURCE]
[SOURCE C]
[PASTE SOURCE]
Real Example: Summarizing Conflicting Reports for a Business Decision
Suppose a company is deciding whether to continue its remote-work policy.
The decision team has four sources:
- Source A: an internal employee survey;
- Source B: a productivity dashboard;
- Source C: interviews with department managers;
- Source D: an external industry report.
The evidence looks like this:
| Source | Main Finding | Type of Evidence |
|---|---|---|
| Employee survey | Employees report higher satisfaction and prefer flexible work | Self-reported employee responses |
| Productivity dashboard | Overall output is broadly unchanged | Internal operational data |
| Manager interviews | Several managers report slower collaboration and onboarding | Qualitative management feedback |
| Industry report | Remote teams show moderate average productivity gains | External multi-company research |
If you ask ChatGPT simply to summarize everything, you might receive:
Overall, remote work has had a positive effect on employees and productivity, although some managers report collaboration challenges.
The sentence sounds balanced, but it makes a subtle error. The company's own productivity data does not show a productivity improvement. The positive productivity finding comes from an external industry report.
A better synthesis would be:
Better synthesis: The available evidence supports a clear employee-satisfaction benefit but a less certain productivity effect. The internal employee survey shows strong support for flexible work, while the company's productivity dashboard indicates that overall output has remained broadly stable rather than increased. Manager interviews raise concerns about collaboration and onboarding, suggesting that the effect may vary by type of work. An external industry report reports moderate productivity gains across remote teams, but that finding should not be treated as proof of the same effect inside this company. The evidence therefore supports higher employee satisfaction more consistently than it supports a company-wide productivity improvement.
The useful result is not a yes-or-no verdict about remote work. It is a clearer picture of what is supported, what is disputed, and what the company may still need to investigate.
Summarizing Sources vs. Synthesizing Sources
When you work with multiple documents, “summarize” and “synthesize” are not quite the same task.
| Task | Summarization | Synthesis |
|---|---|---|
| Main goal | Shorten information | Combine and compare evidence |
| Multiple sources required | No | Usually |
| Compare claims | Not necessarily | Yes |
| Preserve disagreement | Sometimes | Essential |
| Source relationships | Limited importance | Central to the task |
| Best for | Quick understanding | Research and decisions |
If you want ChatGPT to combine multiple sources into one summary, the instruction “synthesize these sources” is often more useful than “summarize these sources.”
But the word alone is not enough. You still need to specify that the model should preserve conflicting evidence, maintain source attribution, and distinguish between agreement and disagreement.
How to Handle Source Quality
Preserving disagreement does not mean treating every source as equally reliable.
A regulatory filing, peer-reviewed study, company blog, anonymous forum post, consultant report, news article, and AI-generated page may all make claims about the same issue. Their existence does not give them equal evidentiary weight.
If your task includes discovering and evaluating sources before the synthesis stage, use the broader Multi-Source Research With AI (Safely Structured) workflow first.
When reviewing source quality, consider:
- whether the source is primary or secondary;
- when it was published or updated;
- what methodology produced the findings;
- whether the author has relevant expertise;
- whether the source has an obvious commercial or institutional interest;
- whether the claim is supported by direct evidence or merely repeated from somewhere else;
- whether several sources actually trace back to the same original dataset or report.
Do not use source count as a substitute for source quality. Three articles repeating the same original claim are not three independent pieces of evidence.
This distinction is particularly important when ChatGPT tells you that “multiple sources agree.” Before treating that as corroboration, check whether those sources are genuinely independent.
Common Mistakes When Summarizing Multiple Sources With ChatGPT
Asking Only “Summarize These Sources”
This instruction tells ChatGPT the desired format but not how to preserve relationships between the sources. For quick reading, it may be enough. For business research, competitor analysis, policy work, or decision support, it is usually too vague.
Better: define the research question, extract claims separately, compare them, and then request the synthesis.
Letting ChatGPT Merge Sources Before Extracting Claims
Once several sources have been blended into one narrative, it is harder to detect whether a qualification or conflicting finding disappeared.
Better: analyze each source separately before requesting any combined conclusion.
Treating Majority Agreement as Proof
If four sources say X and one says Y, ChatGPT may describe X as the obvious conclusion. That can be misleading if the four sources are weak, derivative, or based on the same original evidence while the fifth source is stronger.
Better: evaluate evidence quality as well as source count.
Losing Source Attribution
A statement can remain factually correct while becoming misleading if the reader no longer knows which source supports it.
Better: require explicit attribution for disputed, unique, or decision-critical claims.
Confusing Different Scopes With Disagreement
A global market report and a survey of one local customer segment may produce different results without contradicting each other.
Better: compare geography, population, time period, metric, and methodology before classifying claims as contradictory.
Asking ChatGPT to Decide Which Source Is Correct Too Early
Users often jump directly from “these reports disagree” to “which one should I trust?” But the first question should be why they disagree.
Better: identify differences in method, evidence, scope, and definitions before asking whether one conclusion is better supported.
Ignoring Publication Dates
A newer source does not automatically invalidate an older one, but the date may explain why the results differ.
Better: include dates in the source labels and require ChatGPT to consider temporal differences during comparison.
Trusting Citations Without Opening the Original Source
A citation can make a statement look verified. It does not guarantee that the linked source supports the exact claim, interpretation, or numerical detail in the summary.
Better: verify the most important claims against the original material before using the output for consequential work.
Limits and Risks
A structured workflow can reduce problems in multi-source summarization, but it does not eliminate them.
Hallucinated Connections
ChatGPT may create a logical relationship between two claims even when the sources themselves do not establish that relationship.
For example, one source may report falling sales and another may report declining customer satisfaction. It may be tempting to conclude that satisfaction caused the sales decline, even though neither source demonstrates causation.
Disagreement Compression
When asked to produce a concise answer, the model may compress several competing positions into a softer middle position.
This can make the final summary easier to read while making it less faithful to the underlying evidence.
Attribution Errors
A correct number or finding can be attributed to the wrong source, particularly when several documents contain similar claims.
For decision-critical numbers, return to the original source.
Omission
A finding that appears less central or is supported by only one source may disappear during synthesis. That does not necessarily mean it is unimportant.
This is one reason the final Disagreement Audit should explicitly ask which source-specific or minority findings were omitted.
False Equivalence
Preserving disagreement does not require pretending every position has equal support.
If one conclusion is supported by strong primary evidence and another by unsupported commentary, the final synthesis should preserve both only in a way that accurately represents the difference in evidentiary strength.
Large Input Sets Can Increase Compression Pressure
The more reports, articles, transcripts, spreadsheets, and notes you combine, the easier it becomes for smaller qualifications to disappear from the final answer.
For large research projects, summarize and structure evidence in stages instead of expecting one prompt to process everything reliably.
Old and New Evidence May Not Be Equivalent
When evidence spans several years, a disagreement may reflect changing conditions rather than research error.
Dates should therefore be part of both the source analysis and the final synthesis whenever the topic changes over time.
Citations Still Need Verification
A cited answer is easier to inspect than an uncited one, but citation presence is not the same as citation accuracy.
Check whether the source supports the specific statement being made, including the number, scope, timeframe, and level of certainty.
Important: A source-backed-looking answer is not automatically a source-faithful answer. For important decisions, open the original sources and verify the claims, numbers, dates, and disagreements that materially affect the conclusion.
When to Use ChatGPT Deep Research Instead
The workflow in this guide works especially well when you already have the documents, reports, articles, or excerpts you want ChatGPT to compare.
Deep Research is more useful when the earlier part of the job still needs to be done: finding relevant sources, following several research threads, comparing evidence from different places, and producing a structured source-linked report.
In practical terms, standard chat with supplied sources is a good fit when you can say:
“Here are six documents. Compare what they say about this question.”
Deep Research is a better fit when the task looks more like:
“Investigate this question across current industry reports, company sources, research papers, and other credible evidence, then explain where the sources agree and disagree.”
Deep Research can work across multiple sources, including web material and supplied files, and can return a structured report with source links or citations that make the result easier to inspect.
That does not remove the need for critical review.
A research system can collect more evidence and organize it more efficiently, but the same core questions still matter:
- Are the sources genuinely comparable?
- Do citations support the claims attached to them?
- Are disagreements visible?
- Are strong conclusions based on strong evidence?
- Did the final report turn uncertainty into false confidence?
For source-heavy work, Deep Research can reduce the manual burden of discovery. It does not eliminate the need to inspect disagreement and verify important claims.
A Practical Multi-Source Summary Template
You do not always need a polished narrative. For many work tasks, a structured research note is more useful because it keeps the uncertainty visible.
Research question

Overall finding

Areas of agreement
- ...
- ...

Areas of partial agreement
- ...

Direct disagreements
- Source A:
- Source B:

Important single-source claims
- ...

Why the sources may differ
- ...

What the evidence does not establish
- ...

Sources requiring additional verification
- ...
This structure is especially useful for competitor research, policy analysis, market reports, vendor comparisons, literature reviews, due-diligence notes, and internal decision briefs because it keeps uncertainty visible instead of burying it inside polished prose.
You can also ask ChatGPT to convert the structure into different deliverables after the evidence has been checked: an executive summary, management memo, comparison table, presentation outline, recommendation brief, or meeting note.
The important part is the order. Compress the evidence only after you have made the relationships between sources explicit.
Final Human Responsibility
ChatGPT can organize disagreement. It cannot make the responsibility for interpreting evidence disappear.
Before using a multi-source summary for a meaningful decision, a human reviewer should check whether:
- the original sources are represented accurately;
- the reported disagreements actually exist;
- the data being compared is genuinely comparable;
- a minority or inconvenient finding disappeared from the final summary;
- claims are still attributed to the correct sources;
- a correlation has been turned into a causal explanation;
- a source-specific finding has been generalized too broadly;
- the final conclusion is stronger than the evidence allows;
- important dates, populations, definitions, or limitations were removed during compression.
For low-stakes work, this review may take only a few minutes. For research that influences financial, legal, strategic, medical, policy, or other consequential decisions, verification should be proportionate to the consequences of getting the answer wrong.
There is also a useful mindset shift here.
The goal of multi-source research is not to eliminate disagreement.
Sometimes disagreement is the result.
If five credible sources genuinely reach different conclusions, forcing them into a single answer does not improve the research. It hides what the research actually found.
The goal is not to make five sources sound like one source. The goal is to make the relationship between those five sources easier to see.
FAQ
Can ChatGPT summarize multiple sources at once?
Yes. ChatGPT can analyze and summarize multiple supplied sources, but for reliable synthesis it is better to label each source and explicitly ask the model to identify agreements and disagreements before producing a combined summary. This helps prevent conflicting findings from being blended into a single artificial conclusion.
How do I ask ChatGPT to summarize multiple articles?
Provide or upload the articles with clear source labels, define the question you want answered, ask ChatGPT to extract relevant claims from each source, compare those claims, and only then create the final synthesis. For important research, review the intermediate claim extraction before moving to the final summary.
Can ChatGPT compare conflicting sources?
Yes, but the instruction should explicitly require comparison. Ask ChatGPT to show what each source claims, where those claims conflict, and whether differences in dates, definitions, populations, metrics, or methodologies could explain the apparent disagreement.
How do I stop ChatGPT from blending different sources together?
Assign stable labels such as Source A, Source B, and Source C, require attribution for source-specific claims, and create an agreement and disagreement matrix before requesting a narrative summary. A final Disagreement Audit can then identify distinctions that disappeared during synthesis.
Should ChatGPT decide which source is correct?
Not automatically. First compare the evidence, methodology, date, scope, source quality, and definitions used by each source. If the supplied evidence cannot resolve the disagreement, the final summary should preserve that uncertainty rather than force a single conclusion.
How can I verify a multi-source summary created by ChatGPT?
Compare important claims with the original sources, check numbers and dates, verify source attribution, and look for qualifications or conflicting findings that disappeared from the final text. For important work, run a separate disagreement audit and manually inspect the claims that materially affect the conclusion.