You ask an AI tool to research a market, competitor, regulation, technology, or business decision. Ten minutes later, you have 15 links, dozens of claims, several statistics, and a polished summary. The problem is that you may no longer know which source supports which conclusion.
AI can make research dramatically faster, but speed does not automatically make the research traceable. A source may exist but fail to support the claim attached to it. Two reports may measure different things while an AI summary treats them as equivalent. A statistic may be accurate but outdated. By the time the research reaches a report, presentation, or client document, it can be difficult to reconstruct the path from a claim back to the original evidence.
A source table solves that problem. It creates a structured evidence layer between the material you collect and the conclusions you eventually write. Instead of keeping sources, claims, evidence, limitations, and verification notes scattered across browser tabs and documents, you place them in one research table that AI can help organize and compare.
What Is a Source Table in AI-Assisted Research?
A source table is a structured research table that records where information came from, what each source actually supports, and whether that evidence has been verified. In AI-assisted research, it creates traceability between AI-generated conclusions and the original evidence used to produce them.
A source table is not the same thing as a bibliography. A bibliography answers a basic question: What did I read?
A source table answers more useful questions:
- What claim does this source support?
- What evidence does it provide?
- What population, market, geography, or time period does it cover?
- What are its limitations?
- Does another source disagree?
- Has the relevant evidence been manually checked?
You may also see similar systems described as a source matrix, evidence table, or research matrix. The terminology varies, but the underlying purpose is the same: turn a collection of sources into structured, traceable evidence.
Why AI Research Needs a Source Table
AI tools are good at turning large amounts of information into concise output. That strength can also create a research problem: compression removes detail. When several sources are summarized into a few paragraphs, it becomes easy to lose the difference between what a source explicitly states, what the AI inferred, and what came from another source entirely.
Four problems are especially common.
Fabricated or incorrect citations
An AI system may occasionally produce a citation, URL, title, author, or publication detail that appears plausible but is incomplete or wrong. Even when the source itself is real, specific metadata may still need verification.
A real source can be interpreted incorrectly
The existence of a source does not prove that it supports the sentence attached to it. A report about employee satisfaction, for example, cannot automatically be used as evidence of higher productivity. A market forecast for North America may not support a conclusion about global demand.
Evidence can become outdated
This matters particularly in fast-changing areas such as AI, software, regulation, pricing, market statistics, and technology adoption. A source table makes publication and update dates visible instead of burying them inside browser tabs.
Disagreement can disappear during summarization
If three sources reach different conclusions, a language model may produce a smooth synthesis that sounds more certain than the underlying evidence. A research table makes those conflicts visible before the final summary is written.
If you are still collecting the initial material, start with How to Use ChatGPT for Research Without Fake Sources. The source-table workflow below begins once you have a set of sources worth examining.
What Columns Should an AI Research Source Table Include?
The best structure depends on the project, but a useful research source table should record more than a title and URL. It needs enough information to answer a more important question: why is this source being used?
| Field | Purpose |
|---|---|
| Source ID | Creates a stable reference such as S1, S2, or S3. |
| Title | Records the exact source title. |
| Author / organization | Shows who produced the source. |
| URL / DOI | Provides a direct path back to the original evidence. |
| Publication date | Helps identify outdated or time-sensitive evidence. |
| Source type | Distinguishes research papers, official data, news, company reports, surveys, analysis, and other formats. |
| Main claim | Records the relevant conclusion or statement from the source. |
| Evidence / data | Captures the statistic, result, passage, or finding supporting the claim. |
| Scope | Records population, geography, market, industry, sample, or time period. |
| Limitations | Shows what the evidence does not establish. |
| Verification status | Indicates whether the evidence has been manually checked. |
| Notes | Tracks contradictions, caveats, follow-up questions, or unusual context. |
You do not need every field for every project. A quick competitor scan may need fewer columns than a regulatory review or evidence-heavy strategy report. The important rule is that the table must preserve enough context to prevent a claim from becoming detached from the evidence behind it.
Use stable source IDs. Label sources S1, S2, S3 and keep those IDs throughout the research process. This makes it much easier to trace later summaries, claims, and contradictions back to the original evidence.
Do not ask AI to complete missing fields by guessing. If an author, date, methodology, or other detail is not available in the supplied source, the correct output is “Not stated” or “Not verified”, not a plausible-looking replacement.
How to Build a Source Table With AI Step by Step
The most reliable workflow separates collection, extraction, comparison, and verification. Asking AI to do all four at once makes it harder to see where errors entered the process.
Step 1 — Define the Research Question Before Collecting Sources
A vague question produces a vague table.
Compare these two research tasks:
Too broad: Research remote work productivity.
Better: What evidence published since 2022 shows whether hybrid work affects employee productivity in large knowledge-work organizations?
The second question gives you useful boundaries: date, work model, outcome, organization type, and evidence requirement. Those boundaries determine which sources belong in the table and which columns matter.
For a market analysis, you may need geography and company size. For a policy question, jurisdiction and effective date may matter more. For scientific research, sample size, methodology, and population may be essential.
Step 2 — Collect the Sources Before Asking AI to Compare Them
Whenever possible, give the AI the material you actually want analyzed. That might include:
- web pages and URLs;
- uploaded PDFs;
- official reports;
- research papers;
- copied source text;
- company documents;
- government publications;
- survey results.
This creates a clear evidence boundary. The model is organizing supplied material rather than trying to reconstruct the research from memory.
For work where citations matter, that distinction is important. “Find relevant information” and “extract evidence from these specific sources” are two different tasks. The second is generally easier to audit.
Step 3 — Ask AI to Extract, Not Interpret Yet
Start by converting the source material into a consistent structure. At this stage, the goal is not to decide what the evidence means. The goal is to capture what each source actually contains.
I am building a source table for this research question:
[RESEARCH QUESTION]
Using only the sources I provide, create one row per source.
Extract:
- source ID
- exact title
- author or organization
- publication date
- URL or DOI
- source type
- main claim relevant to my question
- supporting evidence or data
- scope or population
- limitations
Do not infer missing information. Write “Not stated” when the source does not provide a field. Do not add sources that I did not provide.
This kind of extraction prompt is deliberately restrictive. It tells the model to work like a research assistant organizing evidence, not like an expert trying to complete gaps with general knowledge.
Step 4 — Add Claim-Level Evidence
One row per source is useful for an overview, but it can become too coarse when a document contains several independent findings.
Imagine that source S4 contains three findings:
- a statistic about employee turnover;
- a result about productivity;
- a finding about employee satisfaction.
If all three are compressed into one “main claim” cell, later synthesis becomes harder to trace. A better system is to create claim IDs:
- S4-C1
- S4-C2
- S4-C3
This creates claim-level traceability. Each conclusion in the final report can then point back to a specific piece of evidence rather than merely to a document that contains many different findings.
Example: Turning Five Sources Into an Evidence Table
Consider a strategy team researching this question:
Could a four-day workweek reduce employee turnover without hurting productivity?
The team collects five sources. Instead of asking AI to summarize all five immediately, it first builds a research matrix.
| ID | Source type | Relevant claim | Evidence | Limitation | Status |
|---|---|---|---|---|---|
| S1 | Peer-reviewed study | Reports a productivity-related finding. | Specific measured result extracted from the study. | Small or limited sample. | Verified |
| S2 | Company case study | Reports changes in retention after a schedule change. | Internal company results. | Self-reported and organization-specific. | Verified |
| S3 | Employee survey | Reports employee preferences and attitudes. | Survey responses. | Measures attitudes rather than actual productivity. | Verified |
| S4 | News article | Summarizes results from another organization. | Secondary reporting. | Original data not fully reviewed. | Partially verified |
| S5 | Consultancy report | Claims benefits across participating companies. | Aggregated results. | Methodology requires additional checking. | Unverified |
Example: The table immediately shows why “five sources support the four-day workweek” would be a misleading summary. Some sources may measure productivity, others employee sentiment or retention, and their populations and methods may not be comparable.
The point of the table is not to prove or disprove the four-day workweek. Its purpose is to make the evidence visible enough that the team can see what each source actually contributes.
Use AI to Check Which Source Supports Each Claim
Once the sources are structured, reverse the process. Instead of asking, “What does this source say?” ask, “Which source supports this specific claim?”
This is one of the most useful steps in AI-assisted research because it exposes unsupported conclusions before they reach a final document.
Review the source table against the claims below.
For each claim:
- Identify which source IDs directly support it.
- Separate direct support from indirect or contextual support.
- Identify any source that contradicts it.
- Flag claims with no supporting source.
- Do not use your general knowledge to fill evidence gaps.
Return a table with: Claim | Direct support | Indirect support | Contradicting sources | Evidence gap | Verification needed.
This forces an important distinction:
Source relevance is not the same as claim support.
A report can be highly relevant to a topic and still fail to support a particular statement. A source about customer adoption may provide useful context for a market analysis, for example, while offering no evidence for a claim about profitability.
The same applies to quotations and statistics. A citation attached to a sentence should support that sentence, not simply lead to a document about the same subject.
How to Preserve Disagreement Between Sources
A strong source table should not only record agreement. It should make disagreement easier to see.
Suppose three sources produce these findings:
- S1 reports a positive effect.
- S2 reports no meaningful effect.
- S3 concludes that the available evidence is uncertain.
A weak AI summary might reduce this to:
Research generally suggests a positive effect.
That sentence may sound clean, but it removes information that could matter to the decision.
Before synthesizing conflicting evidence, compare:
- methodology;
- sample size;
- population;
- geography;
- publication period;
- definitions;
- measured outcomes;
- data collection method.
Two sources can disagree because one is wrong, but they can also disagree because they are answering slightly different questions. The research table should preserve that distinction.
Once the evidence table is complete, the next task is synthesis. Use the workflow in How to Summarize Multiple Sources With ChatGPT Without Losing Disagreement to combine the evidence without turning conflicting findings into false consensus.
Compare the sources in this table without forcing them into agreement.
Identify:
- findings that genuinely agree
- findings that conflict
- differences caused by methodology, population, geography, definitions, or time period
- questions the available evidence cannot answer
Cite the relevant source ID after every conclusion. If the reason for a disagreement is unknown, say so rather than inferring one.
Add a Verification Status to Every Source
A simple verification field makes the table much more useful because it separates AI processing from human checking.
You can use four practical statuses:
- Verified — the original source has been opened and the relevant evidence has been checked.
- Partially verified — the source exists, but some claim, context, quotation, methodology, or supporting detail still needs checking.
- Unverified — the source or evidence has not yet been manually reviewed.
- Rejected — the source does not support the claim, is unsuitable for the intended use, or contains a material problem.
A green “Verified” label should mean that a human opened the original source and checked the relevant evidence — not that the AI said the source looked reliable.
Avoid invented precision such as an automatic “credibility score: 87/100.” A numerical score can look scientific while hiding subjective judgments about methodology, relevance, expertise, publication quality, and context.
Transparent statuses are more useful because they describe what has actually happened in the workflow.
A Reusable AI Source Table Workflow
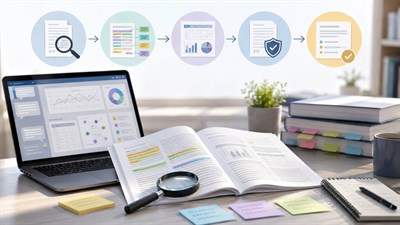
A practical research workflow can be reduced to eight stages:
- Question — define exactly what you are trying to establish.
- Sources — collect the documents, pages, studies, reports, or datasets that may contain relevant evidence.
- Extraction — ask AI to pull consistent fields from the supplied material.
- Source table — organize the information into comparable rows and columns.
- Claim mapping — connect individual conclusions to the evidence that supports them.
- Contradiction check — identify disagreement, incompatible definitions, and evidence gaps.
- Human verification — open the original sources and confirm critical details.
- Synthesis — write the final analysis only after the evidence structure is clear.
You can use the following master instruction when you already have the source material collected.
Act as a research organization assistant, not as an independent source of evidence.
Research question: [QUESTION]
Sources: [PASTE OR ATTACH SOURCES]
Build a source table containing source ID, title, author or organization, publication date, URL, source type, relevant claims, supporting evidence, scope, limitations, contradictions, and verification status.
Rules:
- Use only the supplied sources.
- Do not invent missing citations, URLs, authors, dates, statistics, or quotations.
- Write “Not stated” when information is absent.
- Keep conflicting findings separate.
- Distinguish direct evidence from interpretation.
- Flag every conclusion that requires human verification.
This workflow works particularly well for competitor research, market analysis, internal strategy, policy research, literature reviews, content research, vendor comparisons, and evidence-heavy reports.
Common Mistakes When Building Source Tables With AI
Letting AI Generate the Sources From Memory
If traceability matters, do not treat model recall as the source database. Ask AI to work from explicit documents, links, uploaded files, or verified search results whenever possible.
The more specific the required citation, the more important this becomes. A general explanation may tolerate broad background knowledge. A statistic going into a client presentation needs a traceable origin.
Recording Only the Source Title and URL
A list of links is not yet an evidence table. Without the claim, evidence, scope, and limitation fields, you still have to reopen every source to remember why it was collected.
The goal is not simply to store sources. The goal is to preserve the relationship between the source and the conclusion it may support.
Treating Every Source as Equally Strong
Different sources answer different questions. Official statistics, peer-reviewed studies, company case studies, surveys, vendor reports, expert commentary, and news articles may all be useful, but not necessarily for the same purpose.
A source type should therefore be visible in the table. This does not mean creating a universal ranking where one category is always “better.” The right source depends on the claim being investigated.
Ignoring Publication Dates
An older source can still be valuable, but age matters when the subject changes quickly. Software capabilities, AI models, pricing, regulations, market size, adoption rates, and product features can become outdated quickly.
A publication-date column makes stale evidence easier to identify before it reaches the final report.
Confusing “The Source Exists” With “The Source Supports the Claim”
This is one of the most important distinctions in reliable research.
A valid URL proves that a page exists. It does not prove that the page contains the claimed statistic. A real paper proves that the paper exists. It does not prove that its methodology applies to your population. A government document can be authoritative and still be irrelevant to the specific statement you are making.
Verification therefore has at least three levels:
- The source exists.
- The source is relevant to the topic.
- The source actually supports the specific claim.
For evidence-based work, the third level is the one that matters most.
Asking AI to Resolve Contradictions Automatically
A disagreement is not necessarily an error that needs to be removed. It may reveal a difference in methodology, market, sample, definitions, or time period.
Ask AI to identify and structure contradictions first. Decide how those contradictions affect the final conclusion only after examining the evidence behind them.
Limits and Risks of AI-Generated Source Tables
A well-structured table can still contain bad research. Formatting and accuracy are separate problems.
Common risks include:
- Extraction errors: AI may assign the wrong finding to a field or omit important context.
- Invented metadata: missing dates, authors, titles, or other details may be filled with plausible-looking information if the instruction is not restrictive.
- Incorrect quotations: a passage may be shortened, paraphrased, or reconstructed inaccurately.
- Misread tables: complex tables, footnotes, charts, and multi-column PDFs can be interpreted incorrectly.
- Source-content mismatch: the cited document may discuss the topic without supporting the specific conclusion.
- Missing context: a number may be accurate but refer to a different population, market, period, or definition.
- Outdated evidence: a formerly accurate fact may no longer describe current conditions.
- Secondary-source substitution: AI may rely on a news article or summary when the original report or dataset is available.
- False consensus: conflicting evidence may be merged into a smoother conclusion than the sources justify.
- Filled empty cells: the model may generate plausible information when the source does not contain the requested field.
The key principle is simple:
Structure is not verification.
A clean table can make weak evidence look more authoritative because organization creates an impression of rigor. The table is useful precisely because it makes verification easier, not because putting information into rows and columns makes it true.
Use AI to reduce the organizational cost of research, not to remove the verification step. The more important the decision, the more valuable it becomes to trace important claims back to primary evidence.
What You Still Need to Verify Yourself
Before a source table becomes the basis of a report, recommendation, presentation, article, or business decision, manually check the evidence that matters most.
At minimum, verify:
- that the source actually exists;
- that the URL or DOI points to the correct document;
- the author or publishing organization;
- the publication or update date;
- any quotation you intend to reproduce;
- any statistic used in a conclusion;
- the original context around that statistic or quotation;
- whether the source actually supports the claim;
- whether you are using a primary or secondary source;
- material disagreements between important sources.
You do not necessarily need to verify every minor descriptive detail with the same intensity. Verification effort should reflect the importance of the claim and the consequences of getting it wrong.
A background observation in an internal brainstorming document does not carry the same risk as a number used in an investment decision, compliance document, client deliverable, or public report.
For legal, medical, financial, safety-related, and other high-stakes work, a source table should be treated as an information-organization tool, not as a substitute for qualified professional review.
AI can build the table. It cannot take responsibility for the evidence inside it.
FAQ
What is a source table in research?
A source table is a structured record of research sources and the evidence each one contributes. It can include the source title, author, date, URL, claims, supporting evidence, scope, limitations, and verification status.
Can ChatGPT create a source table?
Yes. ChatGPT can organize supplied sources into a structured table, extract comparable fields, map claims to sources, and flag disagreements. Important information should still be checked against the original sources.
What should be included in a research source table?
At minimum, include a source ID, title, author or organization, publication date, URL, source type, relevant claim, supporting evidence, limitations, and verification status. For detailed research, also include scope, contradictory evidence, and follow-up notes.
What is the difference between a source table and a literature review?
A source table organizes evidence in a structured format, while a literature review synthesizes and explains findings in prose. Building the table first can make the later synthesis easier to trace, compare, and verify.
What is the difference between a source table and a bibliography?
A bibliography records which works were used. A source table also records what each source contributes, which claims it supports, its limitations, and whether the relevant evidence has been verified.
How do I verify sources found by AI?
Open the original source, confirm its title, author, publication date, and URL or DOI, then check whether the relevant passage, statistic, or result actually supports the claim attributed to it. For important conclusions, prefer the original or primary source where possible.
Can AI compare multiple research sources?
Yes. AI can organize sources by methodology, findings, scope, dates, and limitations and identify areas of agreement or disagreement. The comparison is easier to audit when the model works from supplied source material rather than reconstructing evidence from memory.
Should I use one row per source or one row per claim?
One row per source works well for an overview. For detailed research, one row per claim provides better traceability because a single source may contain several independent findings that support different conclusions.